RAG vs Fine-Tuning
The same decision, one row at a time. Use the row that matches the constraint you actually have.
| Focus | Retrieval-augmented generation | Fine-tuning a model |
|---|---|---|
| What it changes | Retrieval-augmented generationThe context the model reads before it answers. | Fine-tuning a modelThe weights of the model, so the behavior is learned. |
| New or changed data | Retrieval-augmented generationIndex the new document, and the next answer can use it. | Fine-tuning a modelPrepare a new training set and train again. |
| Citations | Retrieval-augmented generationEach answer can point to the passage it used. | Fine-tuning a modelThe model cannot show where a learned fact came from. |
| Permissions | Retrieval-augmented generationRetrieval can filter by user, team, or tenant before the model sees the text. | Fine-tuning a modelAnything in the training data can appear for any user of that model. |
| Best fit | Retrieval-augmented generationSupport, internal search, research, and assistants over a knowledge base. | Fine-tuning a modelA strict output format, a domain tone, or a narrow task at high volume. |
Pick the side that matches the job.
Both options are legitimate. The mistake is buying one when the work has the shape of the other.
Choose RAG when
- The answer exists in documents, tickets, records, or a database you control.
- The source content changes daily, weekly, or per customer.
- Users have to see where an answer came from before they act on it.
- Different users are allowed to see different documents.
Choose fine-tuning when
- Good prompts and examples still fail to hold the format or the tone.
- The task is narrow and repeats at high volume, such as labeling or extraction.
- You have a clean set of input and output examples that represents the task.
- The knowledge is stable, and the problem is behavior, not missing facts.
Three checks that settle the decision.
- 01
Name the failure before you pick the fix
If the model does not know your facts, that is a retrieval problem. If it knows the facts and answers in the wrong shape, that is a behavior problem. Fine-tuning does not fix a missing document.
- 02
Build the evaluation set first
Collect real questions and the answers an expert accepts. Measure RAG and any fine-tuned model against the same set. Without it, both options are a demo.
- 03
Plan who updates the knowledge
A RAG system needs an owner for ingestion, re-indexing, and removal of old content. A fine-tuned model needs an owner for the next training run.
When Corpvance is the wrong fit. A one-page marketing site, a staffed seat with no product to ship, or a request that is only design, only advertising, or one integration with no product around it.
Systems that match this kind of decision.
Each card links to the full case study. The reason is why that project belongs on this question.
Transcendence
Premium Holographic Digital Human Platform
Tenant knowledge uploaded as PDFs and text, processed through chunking, embeddings, vector storage, and retrieval into the model context.
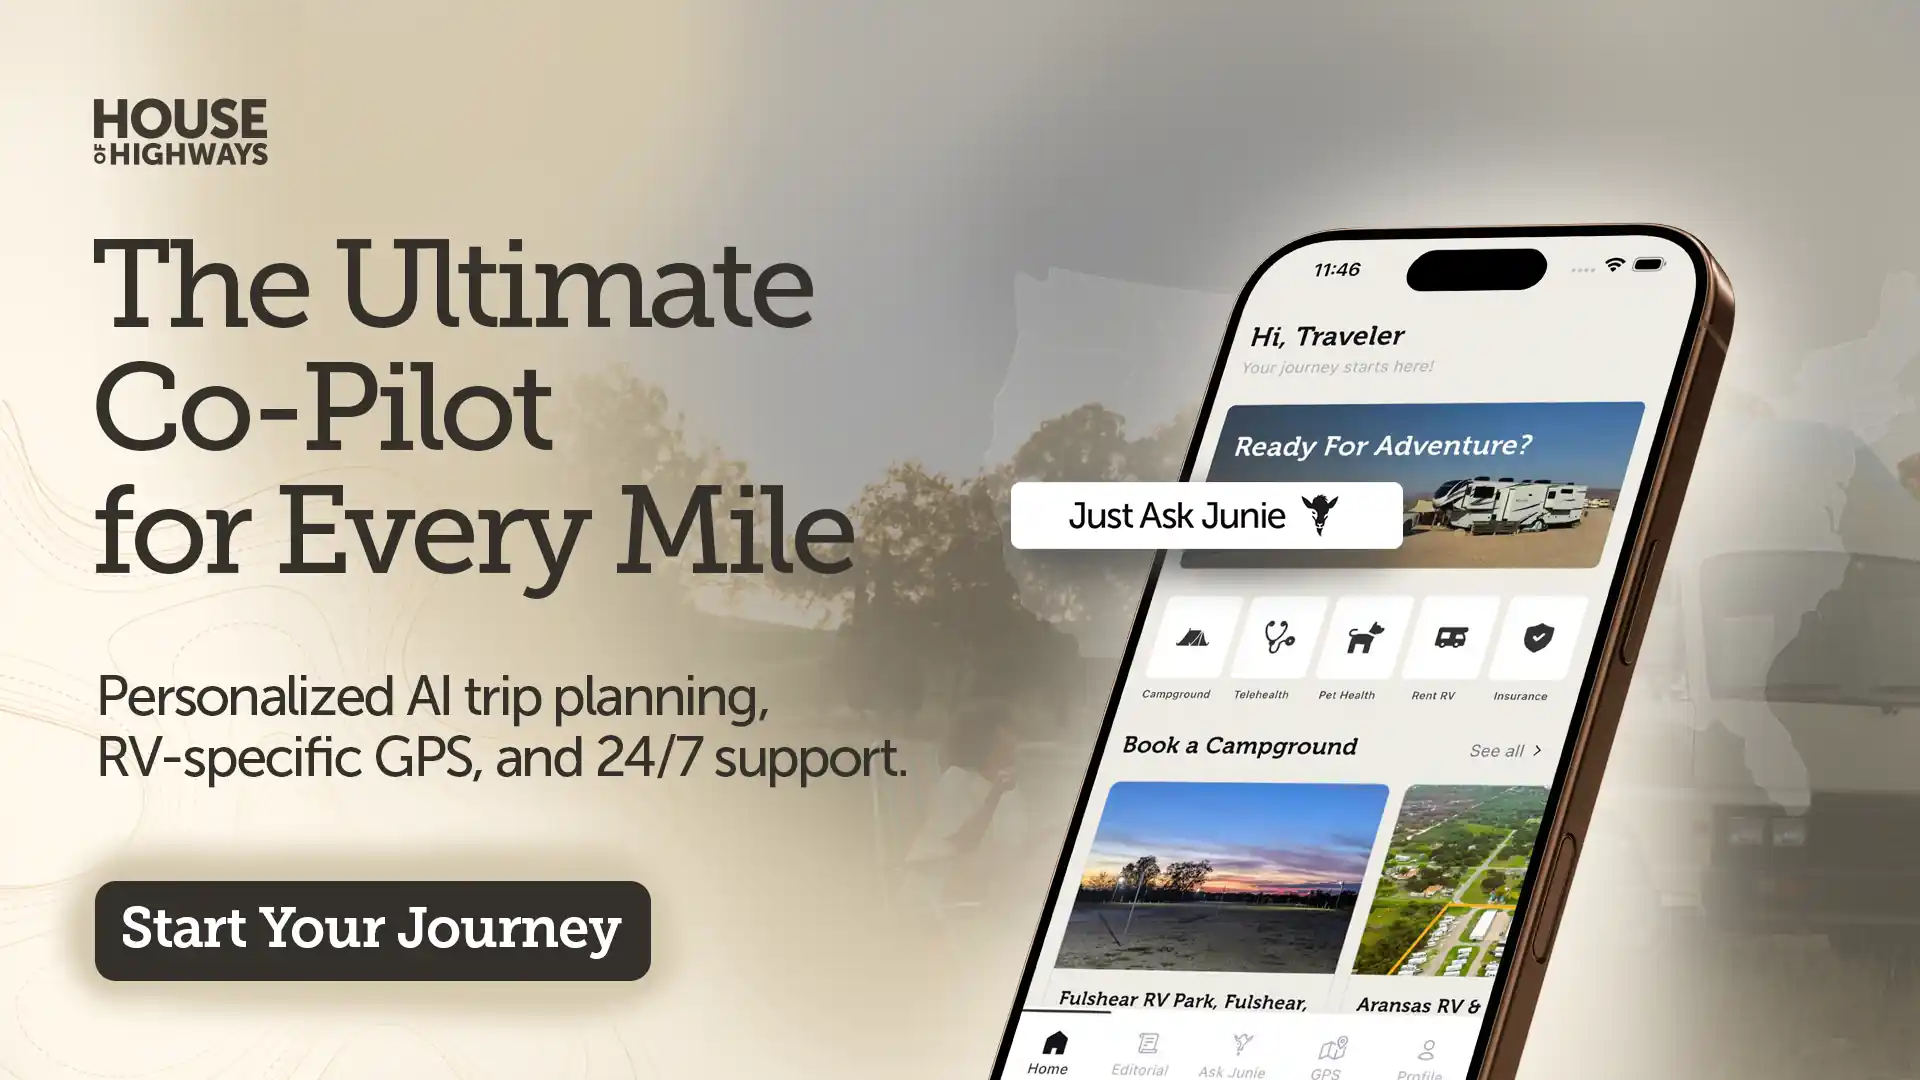
House of Highways
AI Trip Companion for RV Travelers
Trip recommendations generated with RAG over route, vehicle, and preference data that changes with every traveler.
Questions on this decision
The short version of the same choice, in the phrasing people use when they ask.
01Is RAG cheaper than fine-tuning?
Usually, to start. RAG needs an ingestion pipeline, a vector store, and evaluation, but no training run. Fine-tuning needs a clean dataset and a new training run each time the behavior must change. The running cost depends on volume and on the model you use, so compare both on the same evaluation set.
02Can we use RAG and fine-tuning together?
Yes. A fine-tuned model can hold the format or the tone, and retrieval can supply the current facts. Most teams add fine-tuning only after a RAG system is in production and a specific behavior still fails.
03Does RAG stop the model from making things up?
It reduces the risk. The model answers from retrieved passages, and the answer can cite them. A production system also needs a rule for low-confidence retrieval, such as saying it does not know, and an evaluation set that catches wrong answers before users do.